NVIDIA Nemotron 3.5 Bolt E4B on a Korean Document-QA Benchmark: Scored Against Its Base Model, gemma4 E4B
NVIDIA's Nemotron 3.5 Bolt E4B, released October 23, scored on 299 Korean document questions with known answers, side by side with the model it was post-trained from (gemma4 E4B): same retrieved pages, prompt, judge and quantization label, with thinking off and on. Plus GTX 1080 Ti and RTX 3090 speed, and how to turn thinking on in Ollama.
Every number here comes from runs on my own machines. The benchmark and the other models' results are the same as in Local RAG scored on 300 Korean questions. (한국어판: 엔비디아 Nemotron 3.5 Bolt E4B, 한국어 문서 RAG 300문항)
Summary
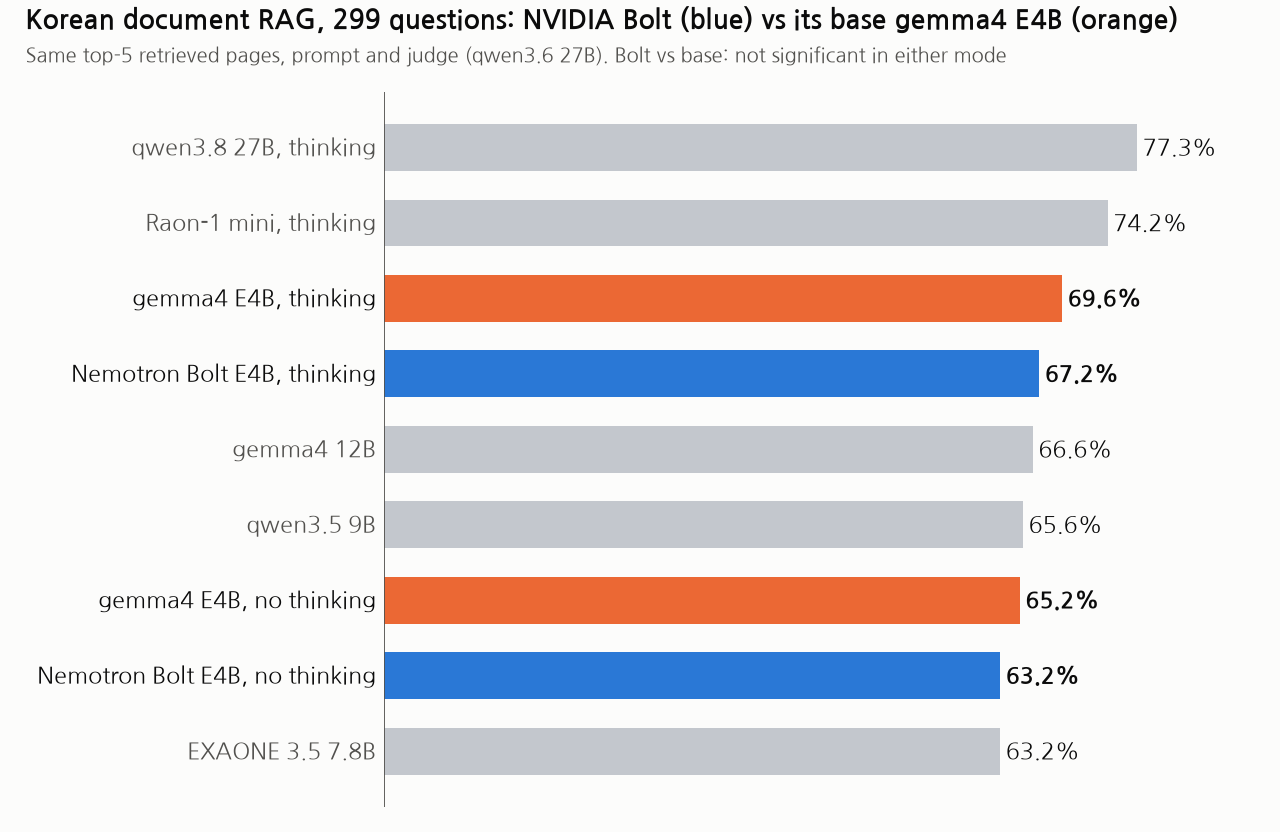
- Accuracy (299 questions): with thinking on, Bolt 67.2% vs its base model gemma4 E4B 69.6%; with thinking off, 63.2% vs 65.2%.
- No difference was detected in either mode (paired test on the same questions, p=0.27 and 0.31). NVIDIA's post-training brought no measurable gain on Korean document QA (the base model was 2 points higher in both modes, within chance).
- NVIDIA reports Bolt about 10 points above the base model on the GaRAGe RAG-grounding benchmark (40.7 vs 30.9 at Q4_K_M). That gap did not show up on this Korean test. GaRAGe is English-centric and scored differently, so this does not mean NVIDIA's number is wrong; it means the gain did not carry over to Korean document QA.
- Thinking adds about 4 points to both models and costs 3 to 4 times the time per question. Bolt with thinking (67.2%) is on par with gemma4 12B (66.6%) and qwen3.5 9B (65.6%).
- The file is 6.2 GB, so by size it fits a single 11 GB GTX 1080 Ti (these runs used a two-card server). On an RTX 3090 it writes about 135 tokens per second.
- Pulled through Ollama, thinking is unavailable. The workaround is below.
What Bolt E4B is
A small model NVIDIA published on Hugging Face on October 23, 2026 (model card).
- Post-trained by NVIDIA from Google's Gemma 4 E4B (instruct). 8B parameters in total, about 4B effective.
- The post-training is reinforcement learning (GRPO) aimed at instruction following, multi-step tool use, multi-turn conversation and structured output, for fast, low-memory voice and on-device assistants.
- The release is one Q4_K_M GGUF of 6.18 GB, despite "4GB" in the name.
- License OpenMDW-1.1, commercial use allowed (the Gemma 4 base is Apache 2.0).
Korean support is ambiguous. The card text lists English, Spanish, French, German, Italian and Japanese "among others"; the card's metadata lists 34 languages including Korean (ko). So I measured it.
NVIDIA's own numbers are measured in reasoning mode (except a few, such as RoleBench). I measured both thinking off and on.
Setup
| Item | Details |
|---|---|
| Test set | Allganize's Korean RAG evaluation set, 300 questions (finance, public sector, medical, legal, commerce); 299 after dropping one with no gold page, plus 20 unanswerable questions I wrote |
| Retrieval | Hybrid (kiwi morphological BM25 + bge-m3) top-5 pages over each domain's documents. Every model gets the same 5 pages |
| Prompt | "Answer only from the excerpts; if the answer is not there, say you cannot find it" |
| Models | Bolt: NVIDIA's Q4_K_M GGUF (6.18 GB) / base: Ollama's official gemma4:e4b (Q4_K_M) |
| Runtime | Ollama 0.40.5, two GTX 1080 Ti, temperature 0, context 16,384 |
| Output cap | 1,024 tokens with thinking off, 8,192 with thinking on |
| Judge | qwen3.6 27B (88.5% agreement with Allganize's verdicts, validated in the earlier post) |
There was no second judge this time. Instead every question where the two models got different verdicts was re-read by an AI reviewer (Claude), below.
Results
| Model | Accuracy | Gold page retrieved | Paragraph | Text | Table | Image |
|---|---|---|---|---|---|---|
| gemma4 E4B, thinking | 69.6% | 81.1% | 86% | 69% | 66% | 32% |
| Bolt E4B, thinking | 67.2% | 78.6% | 83% | 64% | 62% | 33% |
| gemma4 E4B, no thinking | 65.2% | 75.7% | 82% | 62% | 52% | 35% |
| Bolt E4B, no thinking | 63.2% | 74.5% | 83% | 58% | 52% | 26% |
Question counts: paragraph 147, text 45, table 50, image 57. "Gold page retrieved" covers the 243 questions whose gold page was in the top 5. All four runs refused all 20 unanswerable questions, as did every other model compared, so that set does not separate models.
Paired comparison (exact McNemar, 299 questions; "A only" = A right, B wrong)
| Comparison | A only / B only (p) |
|---|---|
| Bolt thinking vs gemma4 E4B thinking | 11 / 18 (0.27) |
| Bolt no thinking vs gemma4 E4B no thinking | 9 / 15 (0.31) |
| Bolt thinking vs no thinking | 23 / 11 (0.06) |
| gemma4 E4B thinking vs no thinking | 22 / 9 (0.03) |
| Bolt thinking vs gemma4 12B | 17 / 15 (0.86) |
| Bolt thinking vs qwen3.5 9B | 23 / 18 (0.53) |
How to read it:
- Bolt and its base model are at the same level. The base model came out 2 points higher in both modes, within chance. That is not proof they are equal; this test is not large enough to detect a difference of this size.
- Thinking helped both, by about 4 points; significant for gemma4 E4B (p=0.03), borderline for Bolt (p=0.06). Median generated tokens including thinking were about 650 for Bolt and 780 for gemma4; neither hit the output cap on any question.
- With thinking on, both 4B-class models are on par with gemma4 12B and qwen3.5 9B from the earlier post.
How much to trust the judge
The 24 questions where the two models' verdicts differed (thinking off) were re-read by an AI reviewer (Claude), not by me in full. It disputed 9 of the 48 verdicts, including identical content graded differently only because of line breaks versus bullets. Re-counting with those corrections gives Bolt 193 vs gemma4 E4B 198 (p=0.30): same conclusion. Disagreement sets concentrate judge errors, so the overall error rate is lower, but a 2-point gap is inside the judge's noise.
Differences worth noting
- Bolt answers more briefly. Median length over the 299 answerable questions: Bolt 99 characters, gemma4 E4B 126. That matches the "Brevity" score NVIDIA highlights.
- Bolt says "not found" slightly more often. With the gold page retrieved, 16 of its answers contained a "cannot find" phrase vs 11 for gemma4 E4B (thinking off, including partial answers with a caveat). Not significant, and worth about one question in score.
- On image questions (text only inside figures), thinking off, Bolt scored 26% and gemma4 35%, but that is 57 questions; treat it as a hint.
Running it in Ollama, and turning thinking on
The card's command works:
ollama run hf.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-E4B-4GB:Q4_K_M
But thinking is then unavailable. Sending "think": true returns does not support thinking (Ollama 0.40.5), because Ollama does not recognize the GGUF's chat template as thinking-capable.
Bolt's template uses Gemma 4's thinking tokens (<|think|>, <|channel>), so re-registering the same file with Ollama's gemma4 format turns thinking on:
# Modelfile
FROM hf.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-E4B-4GB:Q4_K_M
TEMPLATE {{ .Prompt }}
RENDERER gemma4
PARSER gemma4
ollama create bolt-e4b-think -f Modelfile
I checked on 30 questions (thinking off, temperature 0) that this gives the same answers as the original template: 23 were identical character for character, the other 7 differed only in spacing or wording, with the same content. The thinking-off results in this post use the original template; the thinking-on results use this route.
llama.cpp's server (--jinja with chat_template_kwargs.enable_thinking) also enables thinking, but on my GTX 1080 Ti it generated 13 to 15 tokens per second, three times slower than Ollama, so I did not use it here.
Speed: GTX 1080 Ti vs RTX 3090
Medians over the same 30 questions, thinking off, with the whole model confirmed on GPU (prompts were about 3,500 tokens each).
| GTX 1080 Ti (Ollama 0.40.5) | RTX 3090 (Ollama 0.40.2, Windows) | |
|---|---|---|
| Bolt generation | 45 tokens/s | 135 tokens/s |
| gemma4 E4B generation | 94 tokens/s | 138 tokens/s |
| Prompt processing | about 1,130–1,190 tokens/s | about 7,000 tokens/s |
| Per question | 4.5–4.7 s | Bolt 1.1 s / gemma4 1.4 s |
- Bolt's half speed on the 1080 Ti is most likely packaging, not the model. Ollama's official
gemma4:e4bbundles a small draft model (about 78M parameters) for speculative decoding; NVIDIA's Bolt GGUF has none. The main networks have the same architecture (gemma4, 42 layers), though the two "Q4_K_M" files use different tensor mixes (Bolt 6.18 GB with Q8_0 embeddings; gemma4:e4b's main model 5.49 GB, mostly Q6_K). I did not run an A/B test with the draft model switched off. NVIDIA released a separate drafter for Bolt (DFlash) with a llama.cpp recipe, which I did not use. - On the 3090 both generate at about 135 tokens/s; the per-question gap there comes from Bolt's shorter answers.
- On the 1080 Ti the per-question time is nearly equal because reading the 3,500-token prompt dominates.
- With thinking on, the 1080 Ti median per question was 17.6 s for Bolt and 12.9 s for gemma4 E4B (the draft model again).
Limitations
- One run each. The same model on different hardware or versions has flipped about 10 verdicts before, so do not read a 2-point gap as a ranking.
- Q4_K_M only. NVIDIA's own table shows differences between BF16 and Q4_K_M.
- The thinking-off and thinking-on runs used different template routes (see above); the 30-question check found no content difference.
- One LLM judge; only the disagreement set was re-read, by a second AI reviewer, not fully by a person.
- Temperature 0 throughout. The model card recommends temperature 1.0 and top_p 0.95.
- Both files are labelled Q4_K_M but their tensor mixes differ (see the speed section).
- One Korean public-document test set. Tool use, multi-turn conversation and role-play, which NVIDIA targets, were not measured. The conclusion is limited to answering from Korean documents.
Reproduce it
Generation and scoring scripts and per-question verdicts are added to the reproduction bundle from the earlier post. The figure is figs_bolt.py; the thinking runs are chain_bolt_think.sh.
Read next
- Local RAG scored on 300 Korean questions: the benchmark and the other models
- Raon-1 mini on a Korean document-QA benchmark: KRAFTON's MoE on the same test
관련 글
엔비디아 Nemotron 3.5 Bolt E4B, 한국어 문서 RAG 300문항으로 채점해 보니: 바탕 모델 gemma4 E4B와 같은 조건 비교
10월 26일 · 17 min read
Local LLMKrafton's Raon-1 mini on a Korean Document-QA Benchmark: 300 Questions with Known Answers, Run on an RTX 3090 and Two GTX 1080 Tis
10월 22일 · 11 min read
Local LLMBuilding a Fully-Local Research RAG on 2× GTX 1080 Ti + an RTX 3090: 3 Gotchas (CPU Embeddings, the Context Trap, and Not Merging GPUs)
6월 6일 · 6 min read
AI/ML크래프톤 Raon-1 mini, 한국어 문서 RAG 300문항으로 채점해 보니: 3090 한 장·1080 Ti 두 장에서 돌린 결과
10월 22일 · 18 min read